Privacy-Preserving Analytics: How Federated Learning Transforms Education Data
 Nov, 11 2026
Imagine trying to teach a class of 30 students while keeping every single one of their personal details locked in a vault. You need to know who is struggling with algebra or who needs extra help with reading comprehension, but you cannot see their names, their home addresses, or even their specific test scores if those scores reveal too much about their identity. This is the paradox facing modern education technology: we want the insights that big data provides, but we are terrified of the privacy risks it creates. For years, the standard approach was simple-collect all the data into one central server, crunch the numbers, and hope no hackers got in. That model is breaking down.
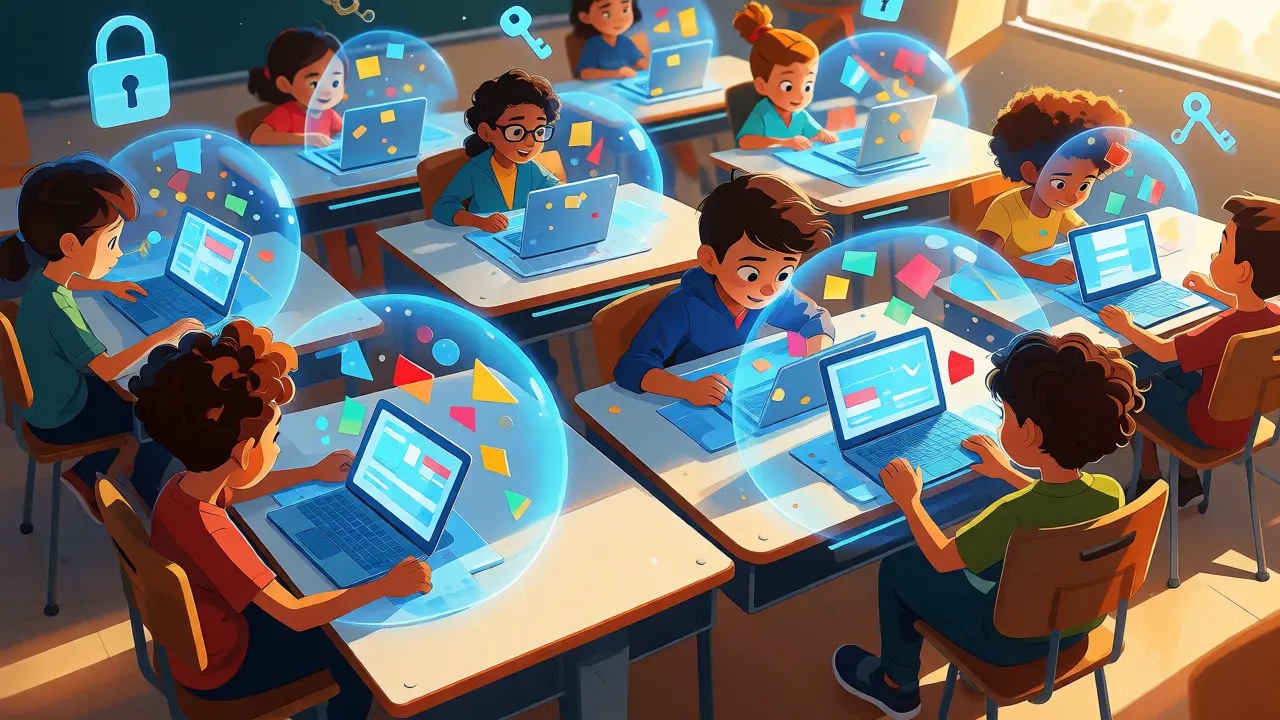
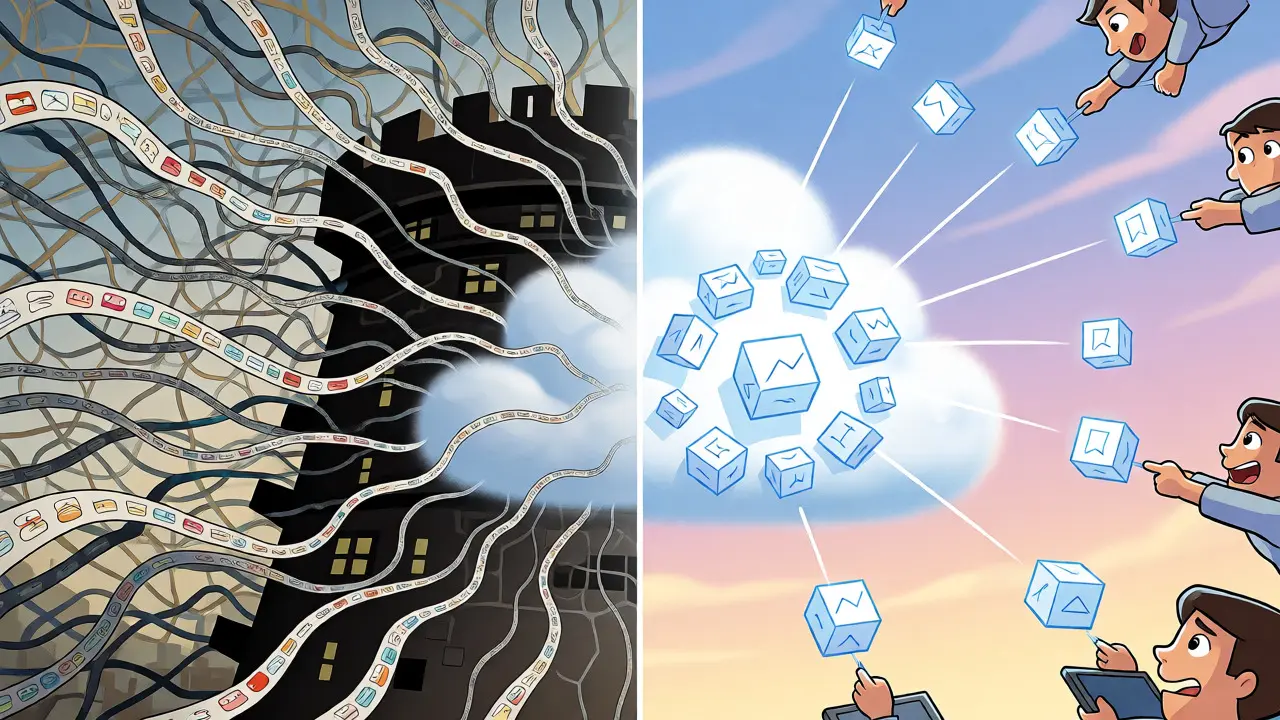
Federated Learning offers a radical alternative. Instead of moving student data to the algorithm, it moves the algorithm to the student's device. Think of it like a group project where everyone keeps their own notes. Each student’s laptop or tablet trains a local version of an AI model using only their own activity. Then, the device sends just the mathematical updates-not the raw data-to a central server. The server averages these updates to improve the global model. No student name ever leaves the device. No essay draft gets uploaded to the cloud. Just pure, anonymized learning patterns.
Why Traditional Data Collection Fails Schools
Schools are not tech companies. They do not have armies of security engineers or massive legal teams to handle data breaches. When a district uses a standard cloud-based analytics platform, they often upload sensitive information: login timestamps, assignment completion rates, and sometimes even text from student responses. This creates a honeypot for cybercriminals. In 2024 alone, several major school districts faced ransomware attacks because their centralized databases held millions of records in one place.
Beyond security, there is the issue of trust. Parents are increasingly wary of how their children’s digital footprints are used. If an ed-tech company stores data on a server in another country, who owns that data? Can it be sold to third parties? GDPR in Europe and FERPA in the United States impose strict rules on this, but compliance is hard when data is constantly moving. Federated learning sidesteps many of these issues by design. Since the raw data never leaves the local device, the risk of exposing personally identifiable information (PII) drops dramatically.
How Federated Learning Works in the Classroom
The process is surprisingly elegant once you strip away the jargon. It starts with a base model-a basic algorithm designed to predict, say, whether a student will pass a quiz based on their past performance. This model is sent to every student’s device via a lightweight app or browser extension.
- Local Training: The student interacts with the educational software. The local model learns from these interactions. If a student consistently fails math problems involving fractions, the local model adjusts its weights to recognize this pattern.
- Update Generation: Once enough data is collected locally, the device calculates how the model should change to better predict future outcomes. These changes are called "gradients." Crucially, gradients are just numbers. They do not contain the actual questions the student answered or the time of day they studied.
- Secure Aggregation: The device sends these gradients to a central server. To add another layer of protection, techniques like differential privacy can add slight noise to these numbers before transmission. This ensures that even if someone intercepts the update, they cannot reverse-engineer the original data.
- Global Update: The server collects gradients from thousands of devices, averages them, and updates the master model. This new, smarter model is then sent back to the devices for the next round of training.
This cycle happens continuously, often overnight or during low-usage periods, ensuring the system improves without interrupting the classroom experience.
Real-World Applications in EdTech
You might wonder, what does this actually look like in practice? Let’s look at three concrete scenarios where federated learning shines in education.
| Feature | Centralized Learning | Federated Learning |
|---|---|---|
| Data Location | All data stored on central server | Data remains on user devices |
| Privacy Risk | High (single point of failure) | Low (distributed storage) |
| Bandwidth Usage | High (constant data uploads) | Low (only model updates sent) |
| Personalization | General trends across population | Adapts to individual + global trends |
| Compliance Complexity | High (cross-border data laws) | Lower (data stays local) |
Personalized Learning Paths: Imagine an adaptive math platform. Traditionally, it needs to know exactly which problems you failed to recommend the next lesson. With federated learning, the platform learns general strategies that work for students struggling with geometry, without knowing specifically that "John Doe" failed problem #42. John still gets the right help, but his specific failure history isn’t mined for advertising profiles.
Early Warning Systems: Schools use analytics to flag students at risk of dropping out. Features might include attendance patterns, late assignments, and engagement levels. A federated model can learn the correlation between these factors across hundreds of schools. One school’s data doesn’t leak to another, but both benefit from the shared intelligence. If School A discovers that irregular login times correlate with lower grades, the global model picks up this insight, helping School B identify similar patterns in their own students.
Natural Language Processing for Writing Assistants: Tools like Grammarly or internal school writing platforms analyze sentence structure. Sending every essay draft to the cloud raises privacy concerns, especially regarding mental health disclosures in creative writing. Federated learning allows the grammar-checking AI to improve its understanding of common errors without storing the actual sentences written by students.
Overcoming Technical Hurdles
It is not all smooth sailing. Implementing federated learning in schools comes with unique challenges. First, hardware variability. Not every student has a high-end laptop. Some might use older Chromebooks or tablets with limited processing power. Running complex machine learning models locally requires optimization. Developers must create lightweight versions of algorithms that can run efficiently on modest hardware without draining battery life.
Second, connectivity issues. Rural schools or districts with spotty Wi-Fi may struggle with the constant synchronization required for federated learning. If a device goes offline for a week, its contribution to the global model is delayed. Robust systems need to handle asynchronous updates gracefully, allowing devices to sync whenever they reconnect.
Third, non-IID data distribution. In statistics, IID stands for Independent and Identically Distributed. In a perfect world, every student’s data would look the same. But in reality, data is non-IID. One classroom might focus heavily on science, while another focuses on arts. Their usage patterns differ wildly. Standard averaging methods can fail here. Researchers use advanced techniques like FedProx or SCAFFOLD to adjust for these differences, ensuring the global model doesn’t bias toward the most active users.
The Role of Differential Privacy
Federated learning keeps data local, but metadata can still leak. If you send an update saying "Model improved significantly," and you are the only user in a small district, someone might deduce your behavior. This is where Differential Privacy enters the picture. It involves adding carefully calculated random noise to the data before it is shared. This noise masks the contribution of any single individual.
Think of it like voting. If everyone votes publicly, you know exactly how each person voted. If you add noise-say, flipping a coin to sometimes report the opposite result-you protect individual votes while still getting an accurate overall tally. In education, this means a teacher sees the class average improving, but cannot pinpoint exactly which student’s recent effort caused the shift. This balance between utility and privacy is tunable; administrators can choose how much noise to add based on their comfort level with precision versus anonymity.
Implementation Checklist for Administrators
If you are considering adopting federated learning solutions for your district, here is a practical roadmap:
- Audit Current Hardware: Check if existing devices support the necessary computational loads. Cloud-based edge computing might be needed for older machines.
- Define Privacy Goals: Decide what level of anonymity is required. Do you need strict FERPA compliance, or are you aiming for higher standards like HIPAA-style protections?
- Evaluate Vendor Claims: Ask ed-tech providers specifically: "Where is the raw data stored?" and "Can you prove the model updates are aggregated securely?" Look for third-party audits.
- Pilot Small: Start with one subject or grade level. Test the impact on device battery life and network bandwidth before scaling district-wide.
- Train Staff: Teachers need to understand that the AI is learning from their students collectively, not surveilling them individually. Clear communication builds trust.
The Future of Ethical AI in Schools
We are standing at a crossroads. On one path, we continue collecting vast amounts of student data, risking breaches and eroding parental trust. On the other, we embrace technologies like federated learning that respect privacy as a fundamental right, not just a regulatory hurdle. The latter path is harder to implement initially but pays off in long-term sustainability.
As AI becomes more embedded in daily instruction-from grading essays to recommending textbooks-the demand for privacy-preserving analytics will only grow. Students today are digital natives; they expect transparency. By shifting the paradigm from "data collection" to "model collaboration," schools can harness the power of artificial intelligence without sacrificing the intimacy and safety of the learning environment.
Does federated learning slow down student devices?
Modern implementations are optimized to run in the background, often during idle times or charging cycles. While there is a slight computational overhead, efficient algorithms minimize the impact on battery life and performance, making it negligible for most modern laptops and tablets.
Is federated learning completely anonymous?
Not entirely, but it significantly reduces risk. Raw data stays local, but model updates can theoretically reveal some patterns. Combining federated learning with differential privacy adds noise to these updates, making it extremely difficult to link specific insights back to individual students.
What happens if a student device breaks or is lost?
Since the raw data resides on the device, losing it means losing that specific historical record unless backed up locally. However, the global model retains the generalized learning patterns contributed by that device prior to loss. Districts often pair FL with secure local backups to mitigate this risk.
Can teachers still see individual student progress?
Yes. Teachers view dashboards generated from local data processed on the student’s device or synced securely. The key difference is that the analytical engine driving recommendations operates globally without needing to store the raw behavioral logs centrally.
Is federated learning compatible with existing LMS platforms?
Many Learning Management Systems (LMS) are integrating FL capabilities via APIs. While full integration varies by vendor, plugins and extensions allow schools to adopt FL principles without replacing their entire infrastructure immediately.